Omni-modal humanoid motion
Movens-ZeroScaling Humanoid Motion Foundation Models with Large-Scale Human Videos
1Zhejiang University2Unitree Robotics3Joint Laboratory of Embodied Intelligence, ZJU & Unitree Robotics
4Bit Oasis5HiThink Research6Microsoft Research7East China Normal University
8Peking University9National University of Singapore
* Equal contribution✉ Corresponding author
01 / Full film
See Movens-Zero in motion.
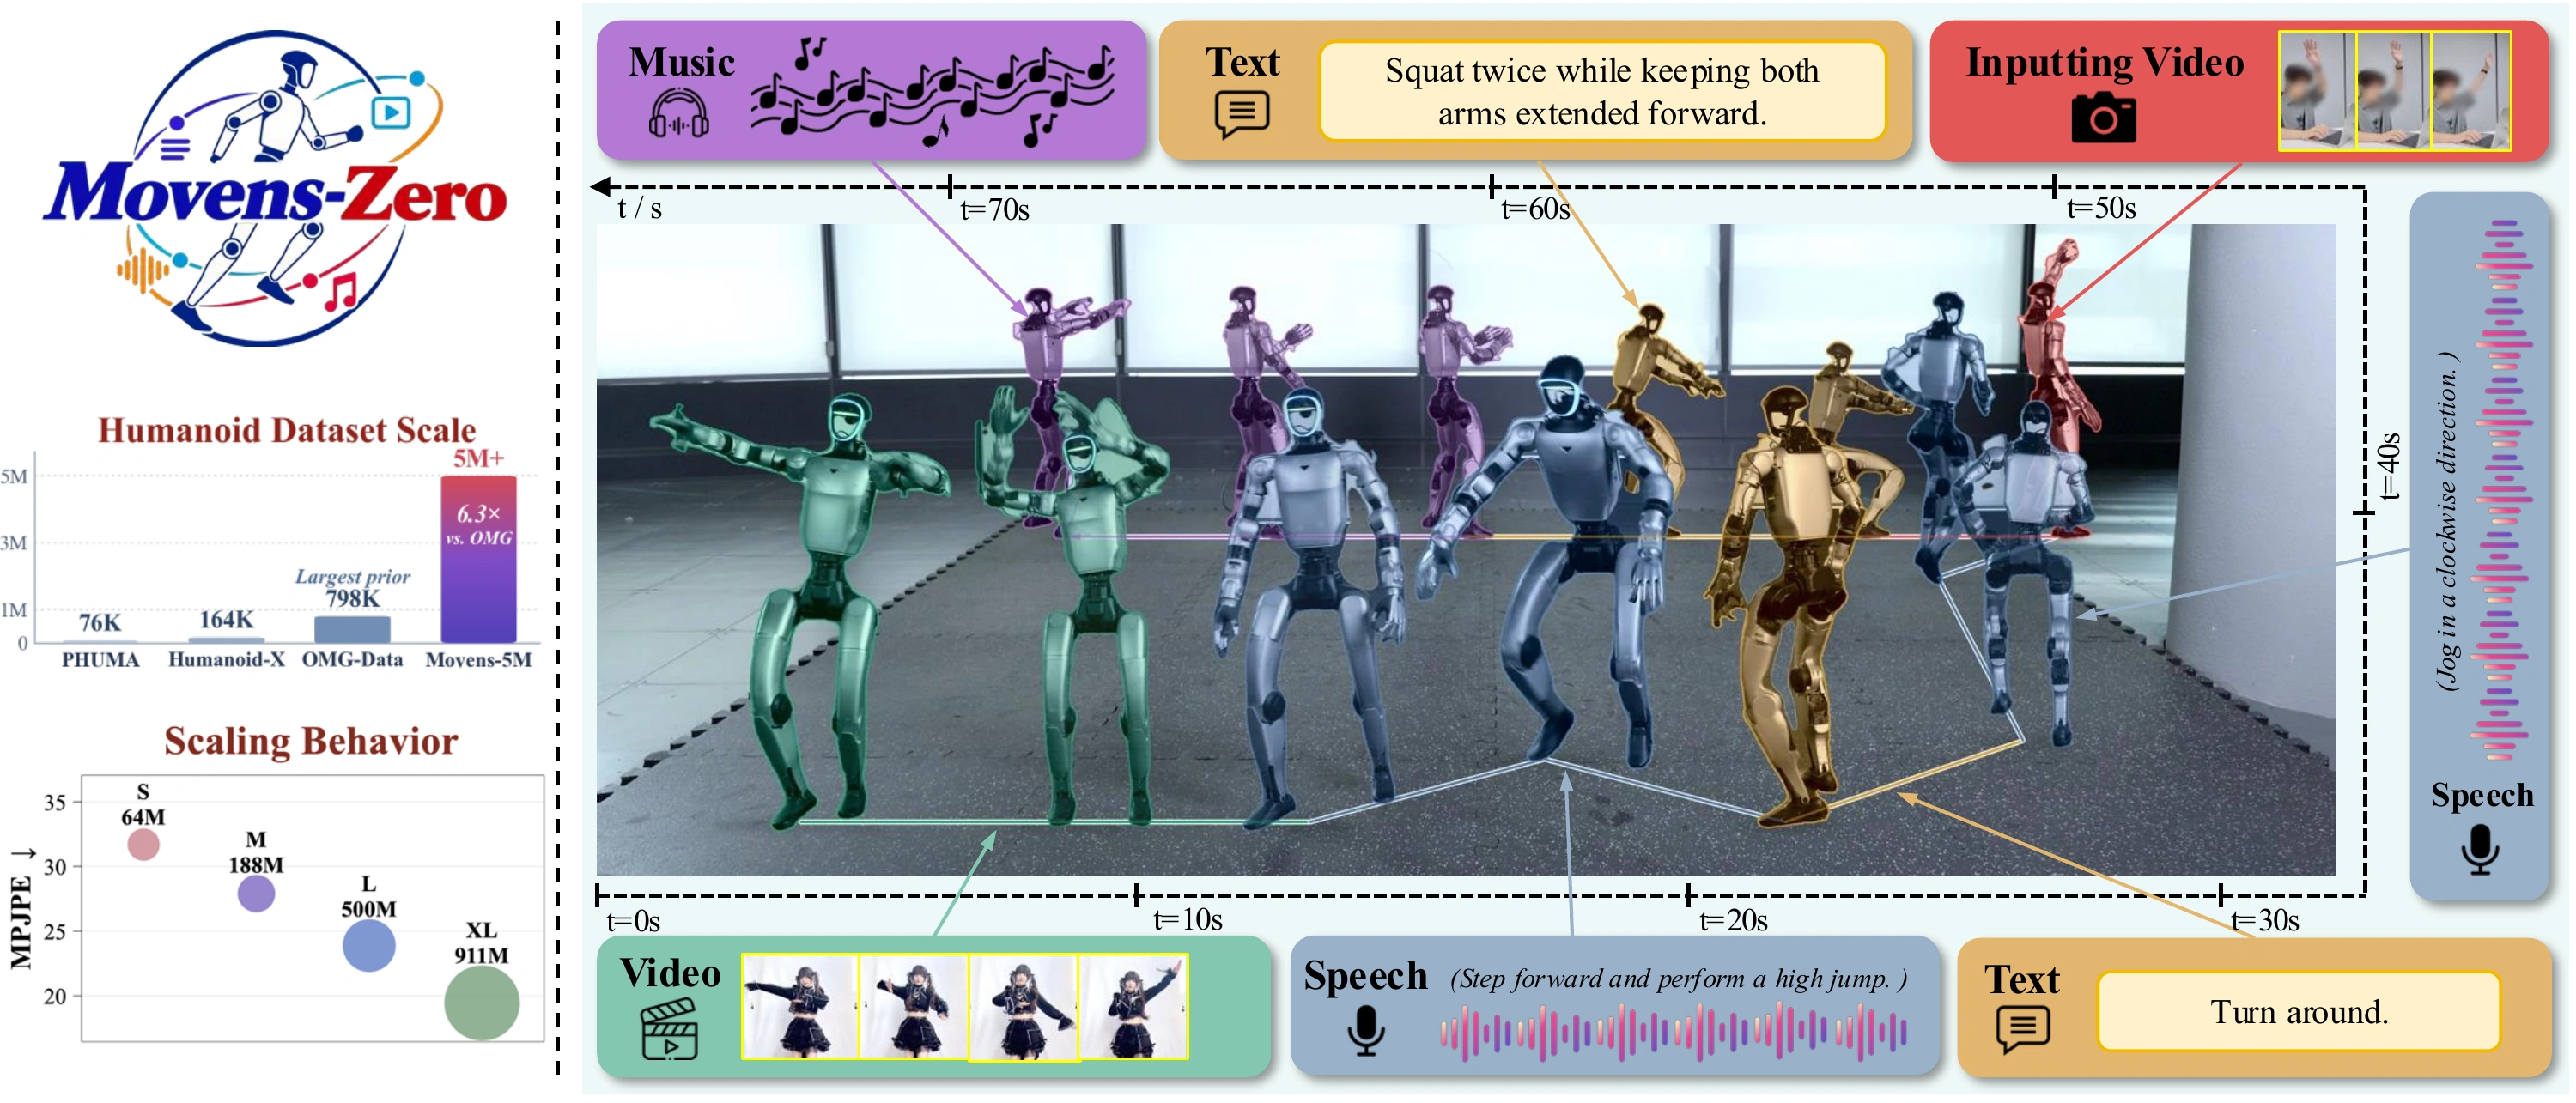
A five-minute real-robot film spanning live and Internet video, spoken instructions, music, and text prompts.
02 / Why Movens-Zero
Human behavior, translated for humanoids.
Motion capture is precise but difficult to scale. Internet video is diverse, yet reconstructed motion can be noisy, physically invalid, or impossible for a humanoid to execute. Movens-Zero bridges that gap.
Web-scale data engine
Recover, repair, retarget, and verify motion from raw video.
Omni-modal supervision
Text, RGB video, speech, and music share one motion space.
Closed-loop generation
Replan from the latest condition and robot state in real time.
03 / Dataset
Human behavior at humanoid scale.
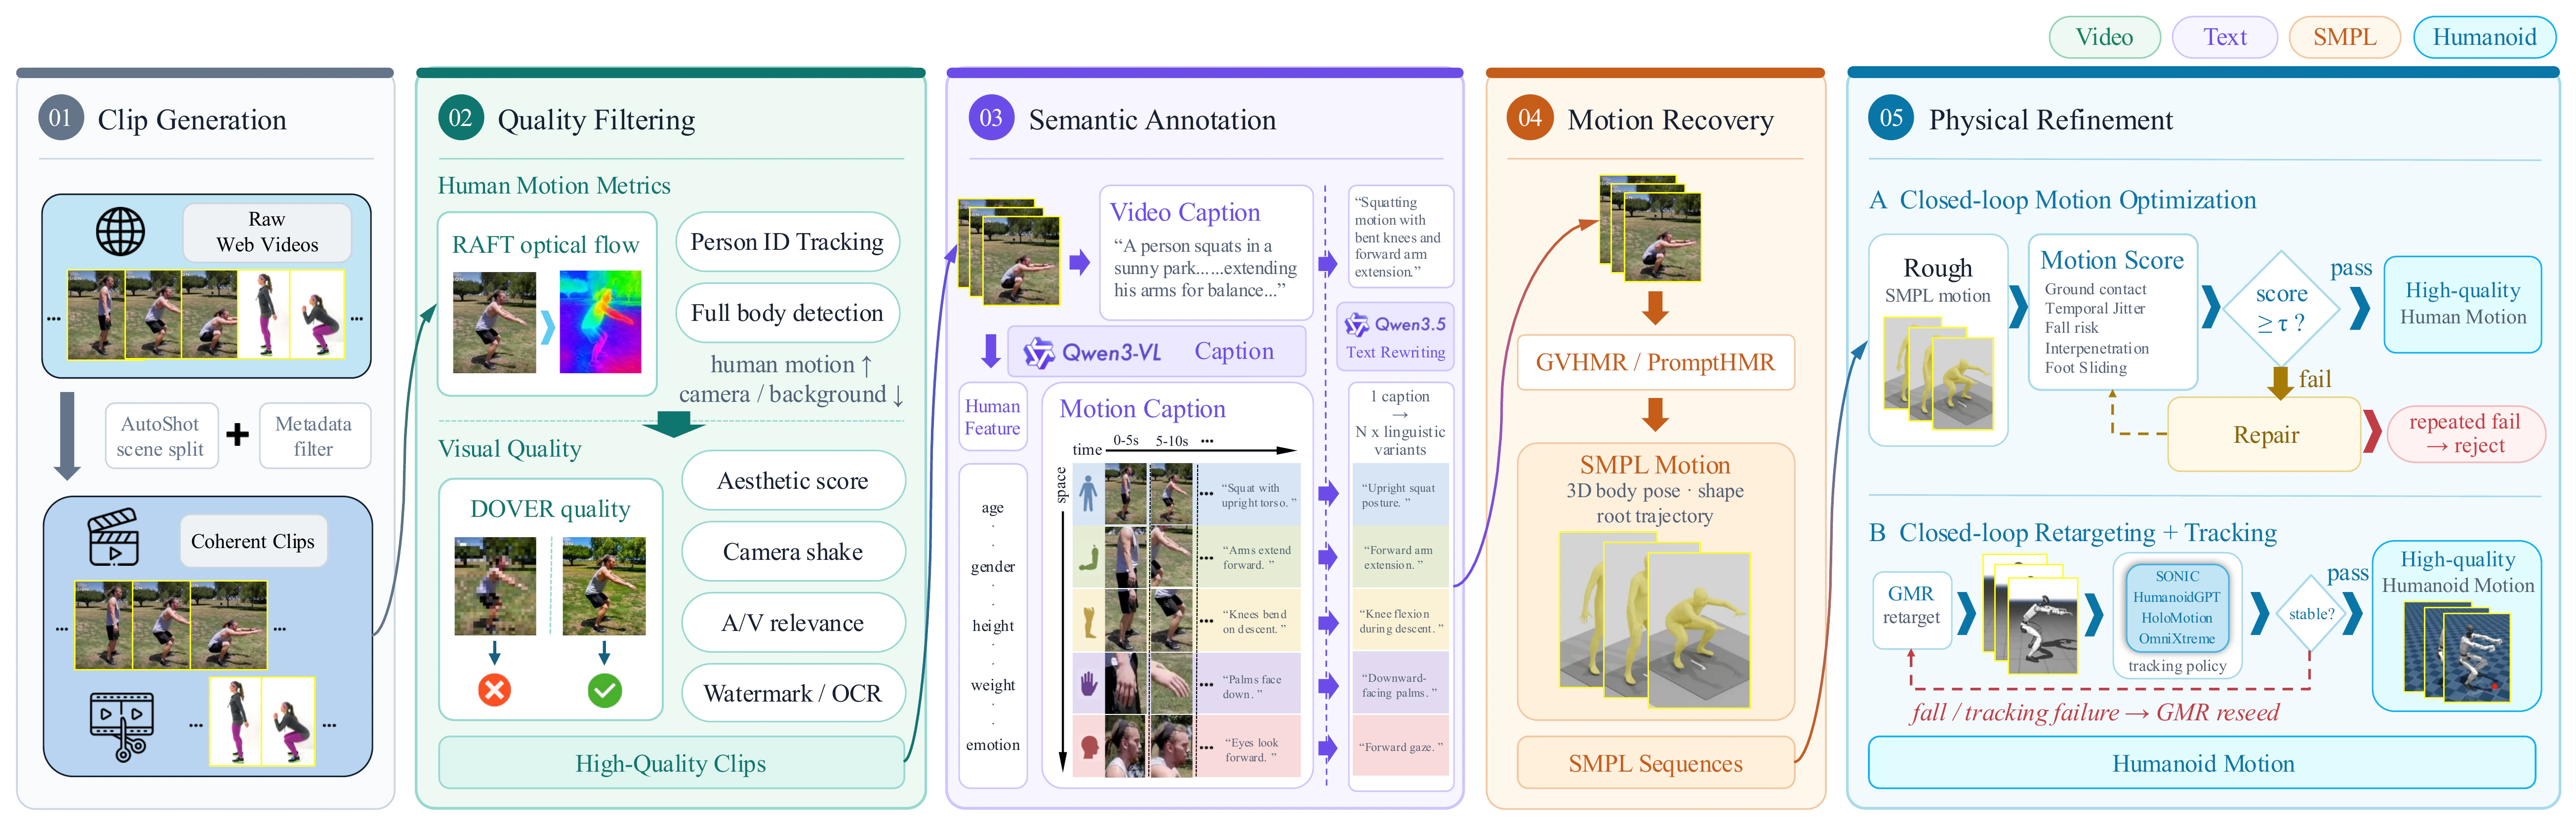
The Movens dataset is built from raw Internet video. Its data engine filters and annotates clips, reconstructs human motion, repairs physical artifacts, retargets behavior, and verifies execution before training.
Data engine
From raw video to executable motion
A five-stage data engine starts from raw Internet video, curates coherent clips, filters motion and visual quality, aligns multimodal semantics, recovers and retargets human motion, and finally refines it through closed-loop execution. Each stage narrows the gap between visually plausible human behavior and motion a humanoid can reliably track.
- 01Clip generationCoherent clips from segmented and filtered web video
- 02Quality filteringHuman-motion and visual-quality screening
- 03Semantic annotationVideo, text, speech, and music alignment
- 04Motion recoveryHuman reconstruction, repair, and retargeting
- 05Physical refinementClosed-loop optimization and execution verification
Human–object interaction
Rich interactions with everyday objects.
Movens-5M includes diverse whole-body interactions with objects, from lifting and carrying to swinging and throwing. Paired human and G1 views highlight this richness across daily activities and exercise.
G1 by default · Hover or tap a case to compare SMPL-X motion.
Inside one Movens record
From a human video to executable humanoid data.
Each showcase example pairs the source clip with recovered human motion, a retargeted humanoid reference, and a tracking rollout. Together, the eight records illustrate diverse motions, scenes, and objects.
01Original video02SMPL rendering03G1 retargeted04G1 tracking
Dataset profile
Scale is visible in the distribution.
Four views summarize temporal scale, behavior taxonomy, scene coverage, and the relationship between motions and their contexts.
Duration at scale
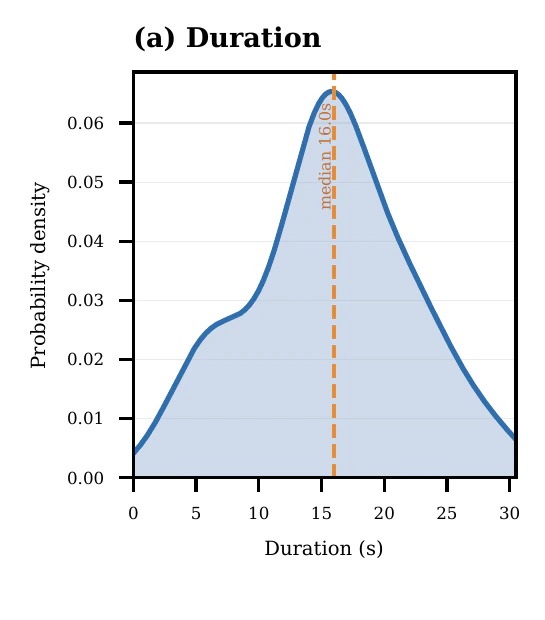
A median duration of 16.0 seconds preserves meaningful temporal behavior while supporting web-scale processing.
A hierarchical motion vocabulary
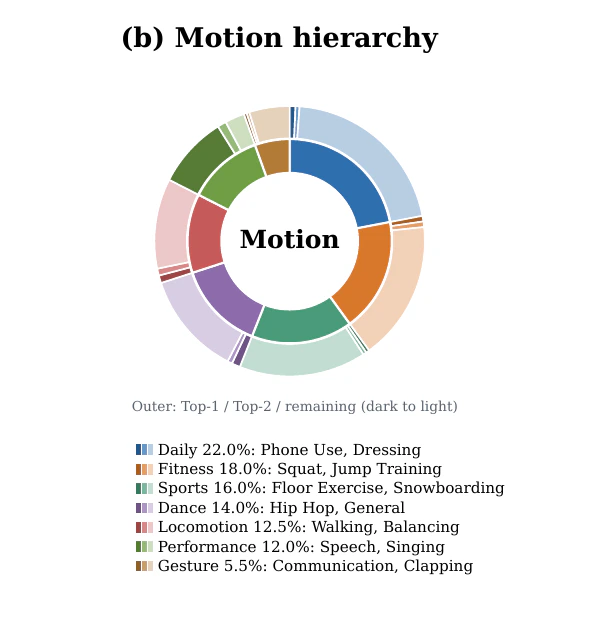
Performance, dance, daily activity, locomotion, fitness, gesture, and sport form a broad long-tail taxonomy.
Behavior in context
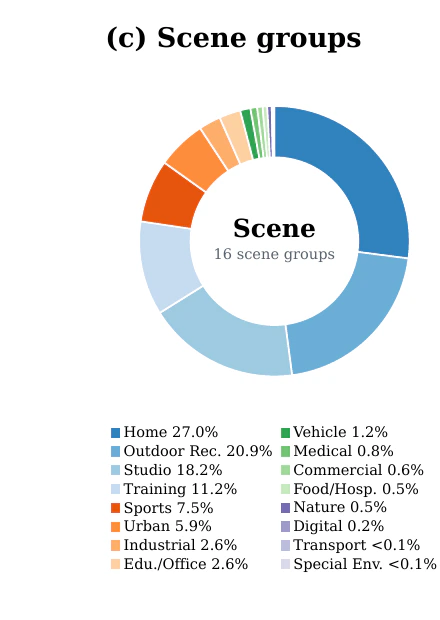
Studio, home, outdoor, stage, fitness, and public settings keep motion grounded in diverse visual contexts.
Diversity beyond raw counts
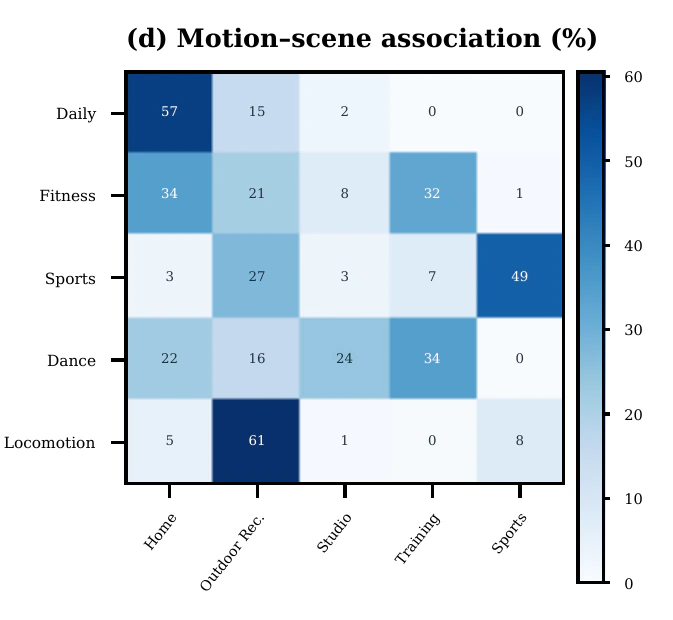
The same motion families appear across multiple environments, reducing dependence on a single visual setting.
Motion-space visualization
Motion diversity, from clusters to clips.
A qualitative view of G1 motion space connects cross-dataset distributions with fine-grained Movens-5M categories and their source-video examples.
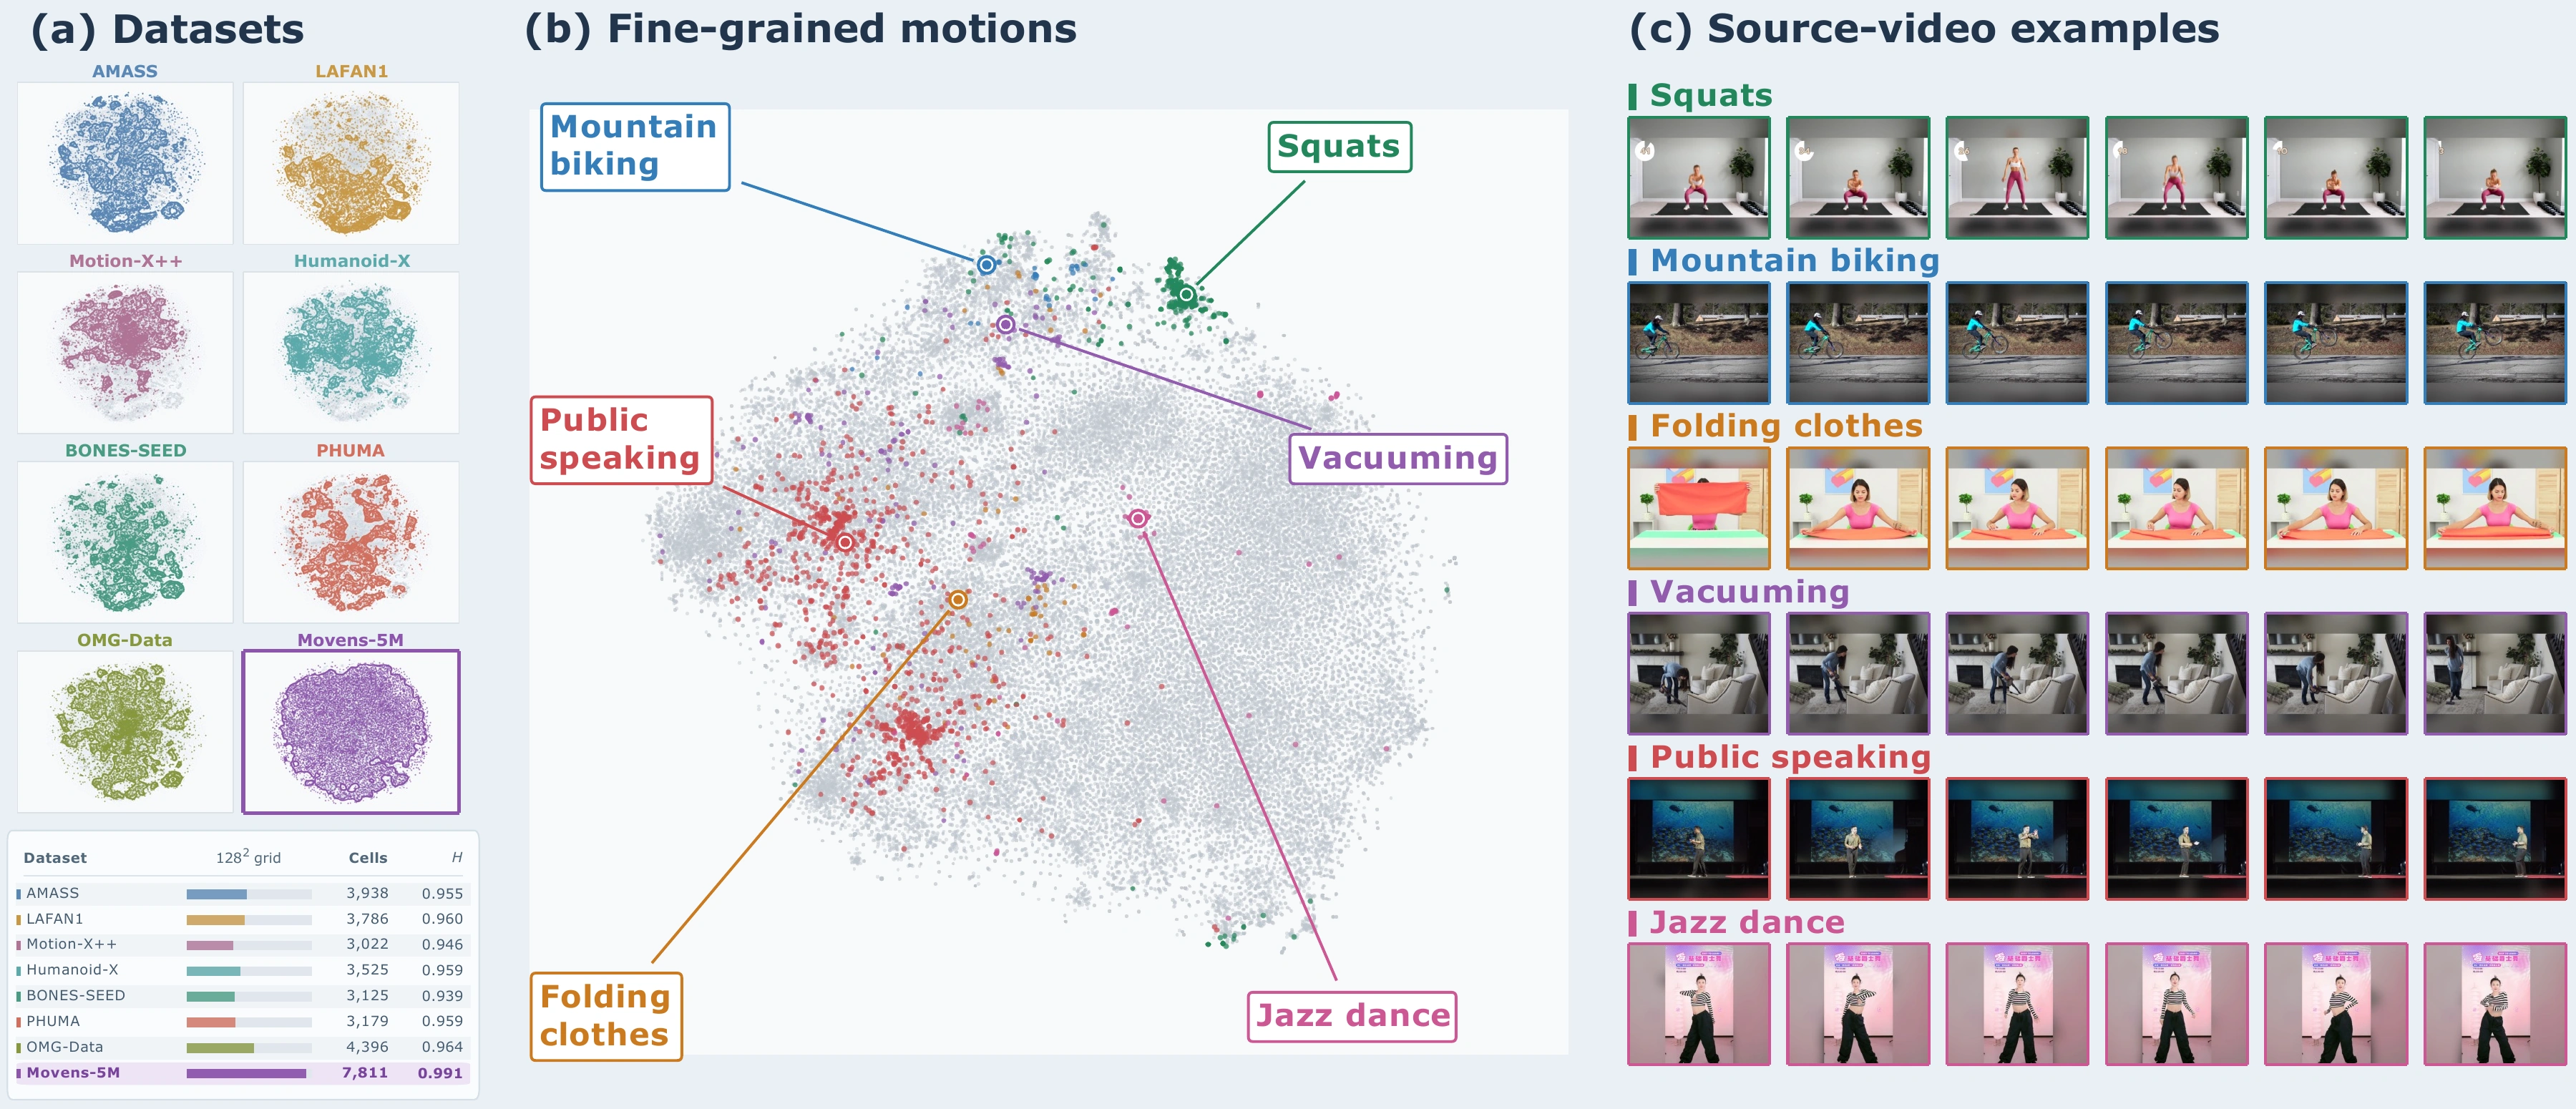
04 / Method
One model, many ways to express intent.
A frozen omni-modal context encoder conditions a shared flow-based action expert. The latest robot state keeps generation grounded in what the hardware is actually doing.
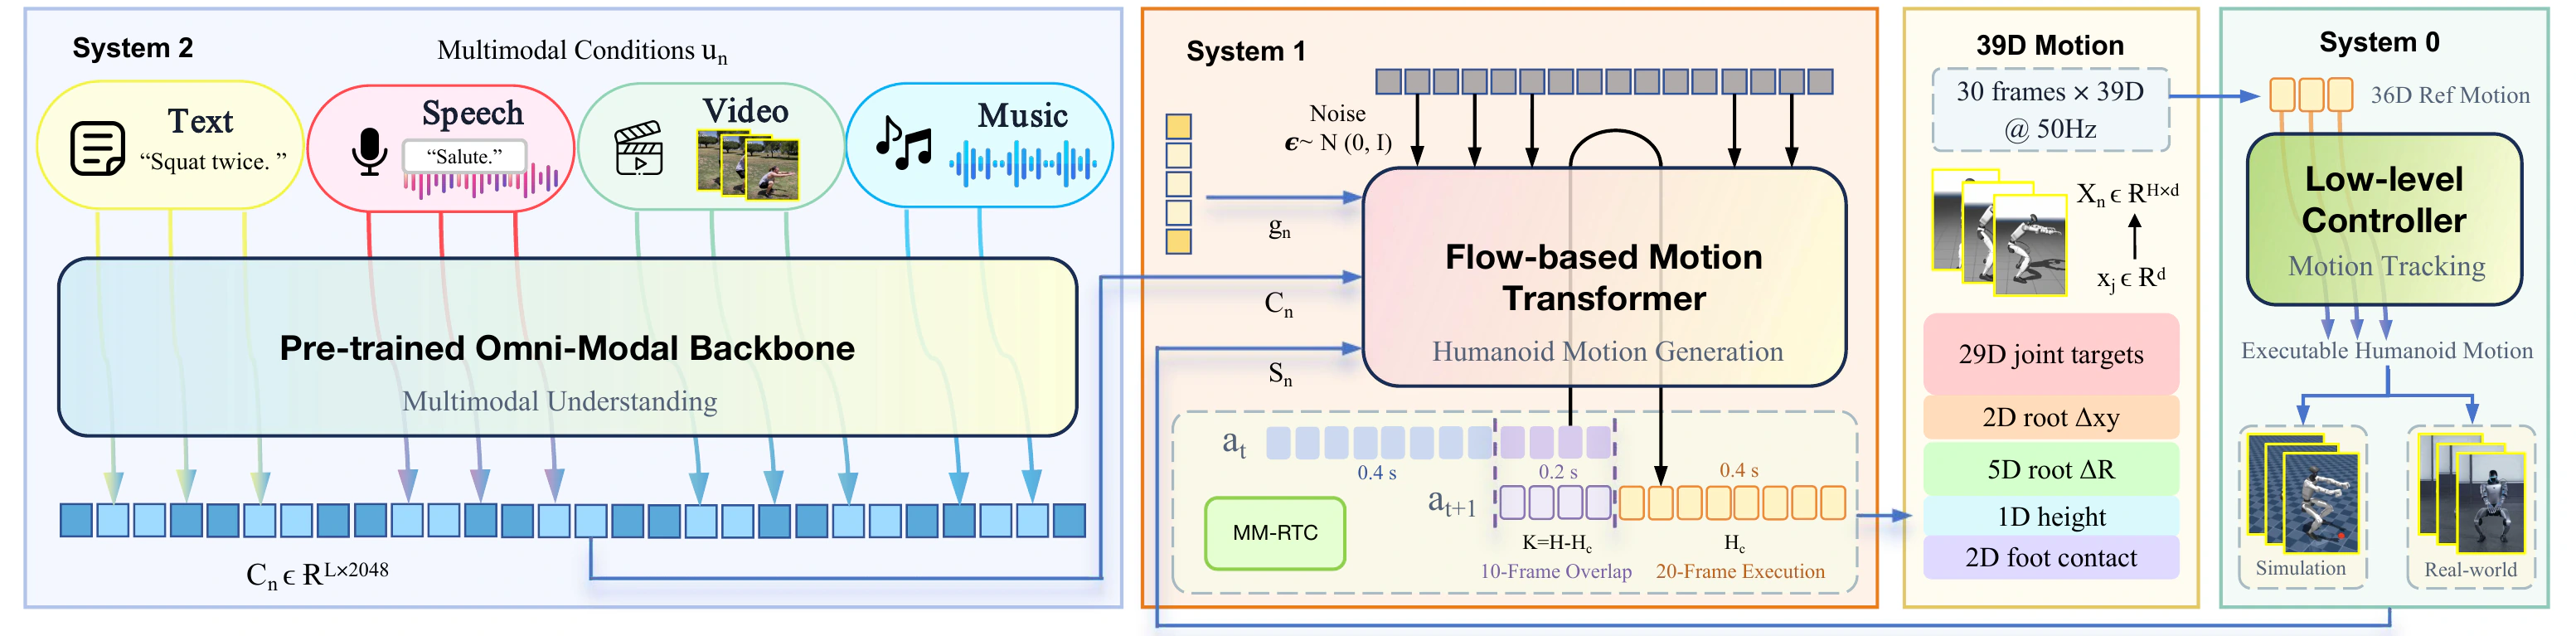
Task-mixed flow matching
Every modality trains one reusable motion prior instead of an isolated policy.
Multimodal real-time chunking
Overlapping predictions enable continuous replanning without abrupt transitions.
State-conditioned generation
Each chunk uses the newest robot state before a high-frequency controller tracks it.
05 / Scaling study
Scaling data, models, and execution together.
The study varies data from 1% to 100% of Movens-5M and the action expert from 64.2M to 910.5M parameters under a shared execution protocol.
Data × model size
Validation FM loss
1%3%10%30%100%training data
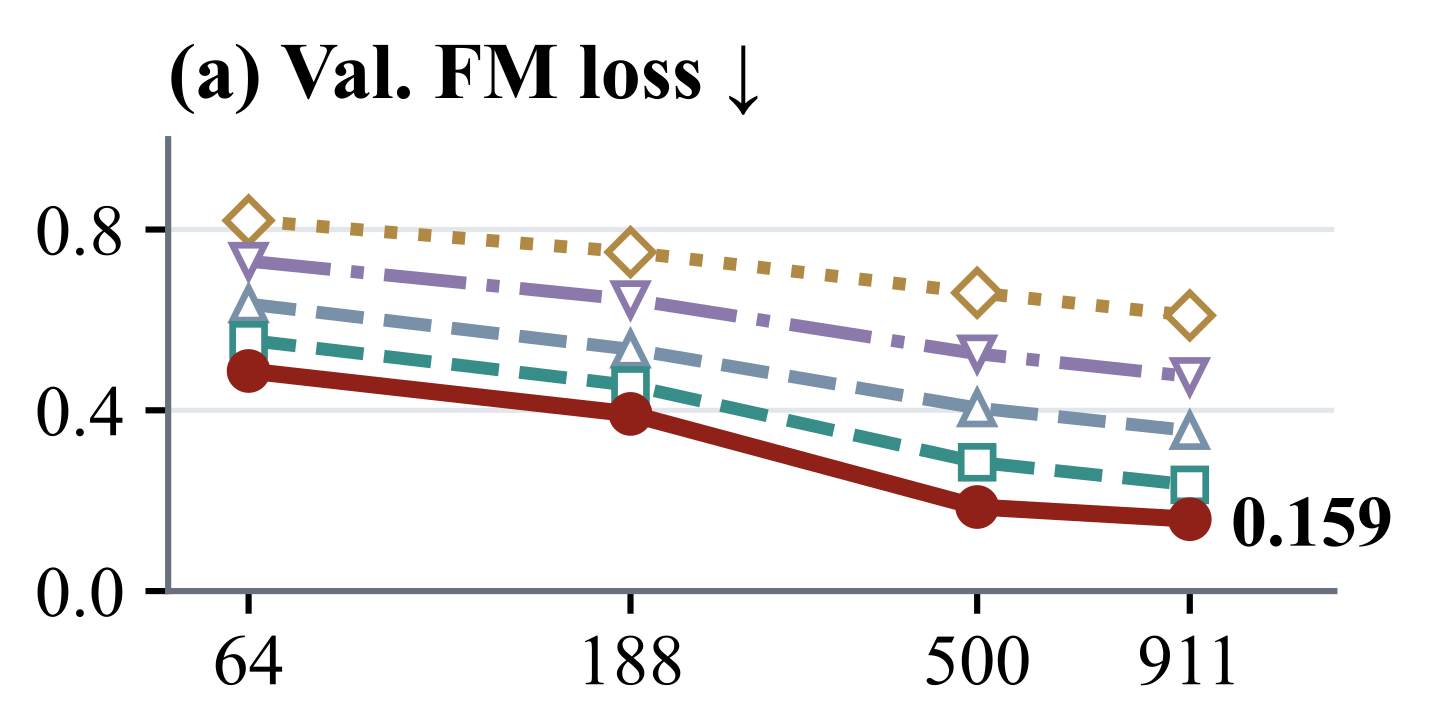
Action-expert parameters · millions · log scale
10% → 100% training data
More data, greater gains.
Relative reduction in Validation FM loss at each fixed model size.
Rounded percentages as reported in the paper.
Data × model size
Text R@3 (%)
1%3%10%30%100%training data
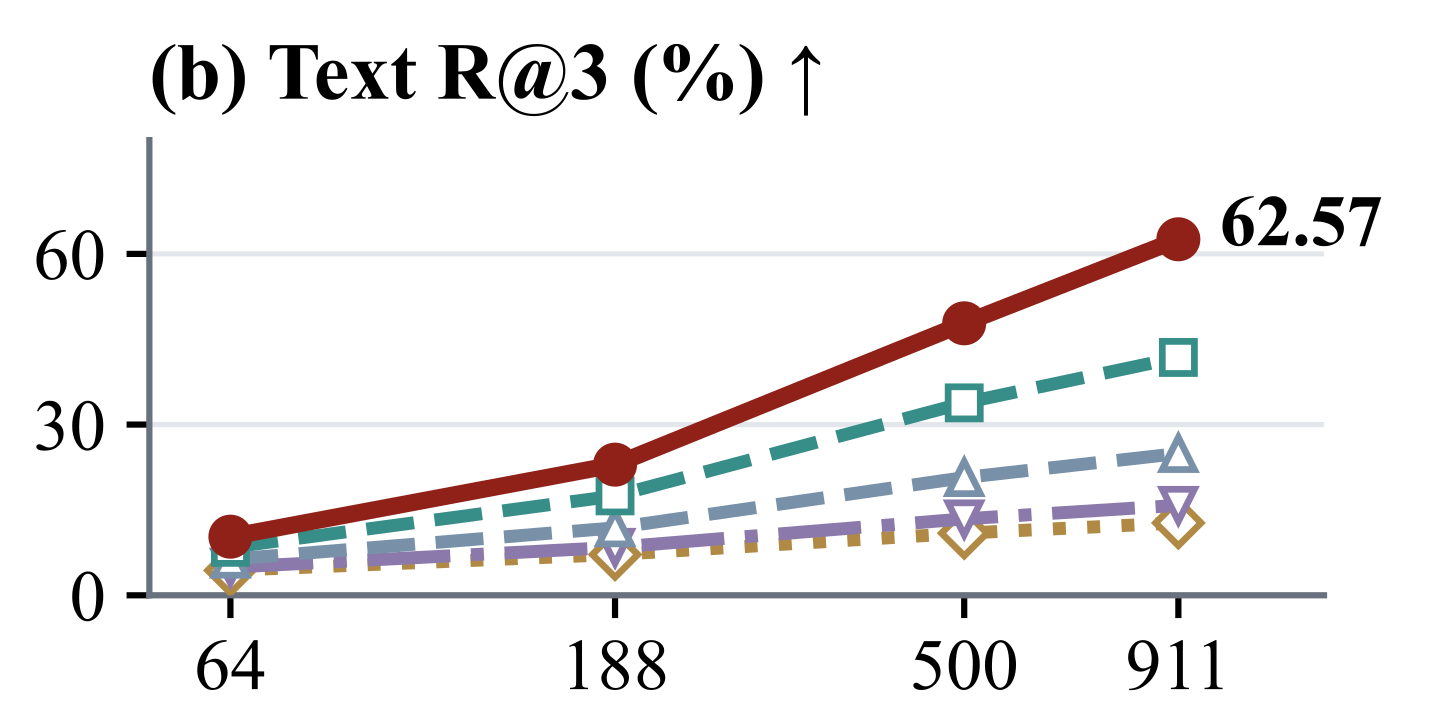
Action-expert parameters · millions · log scale
10% → 100% training data
More data, greater gains.
Relative improvement in Text R@3 at each fixed model size.
Rounded percentages as reported in the paper.
Data × model size
Video MPJPE (mm)
1%3%10%30%100%training data
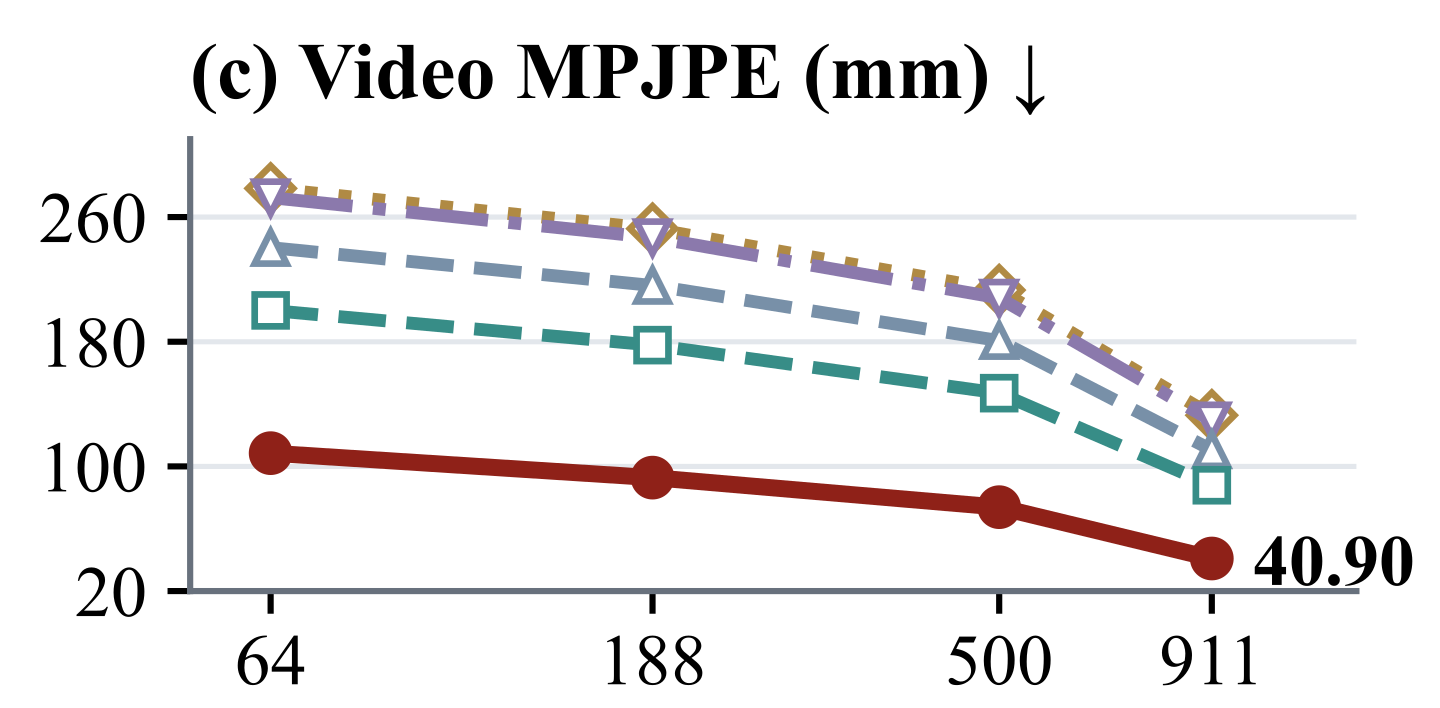
Action-expert parameters · millions · log scale
10% → 100% training data
More data, greater gains.
Relative reduction in Video MPJPE at each fixed model size.
Rounded percentages as reported in the paper.
Data × model size
Audio BeatAlign
1%3%10%30%100%training data
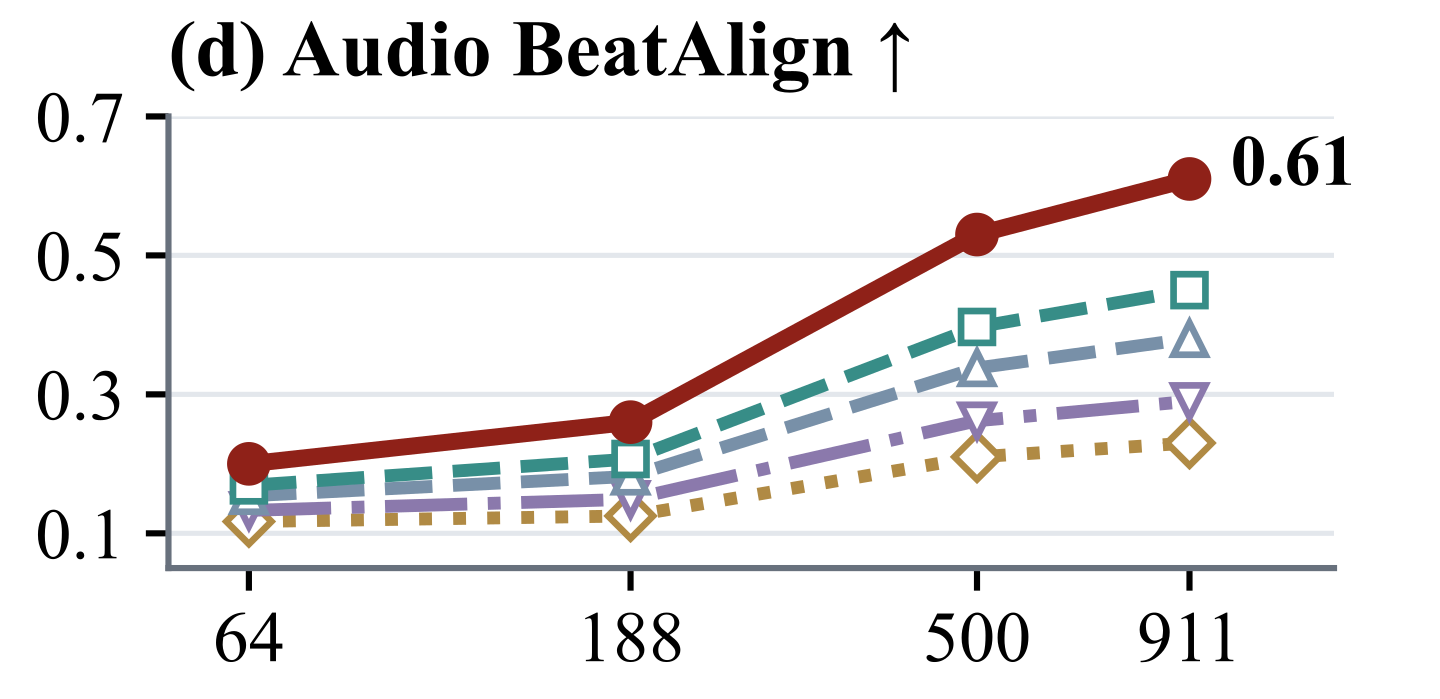
Action-expert parameters · millions · log scale
10% → 100% training data
More data, greater gains.
Relative improvement in Audio BeatAlign at each fixed model size.
Rounded percentages as reported in the paper.
Data × model size
Speech R@3 (%)
1%3%10%30%100%training data
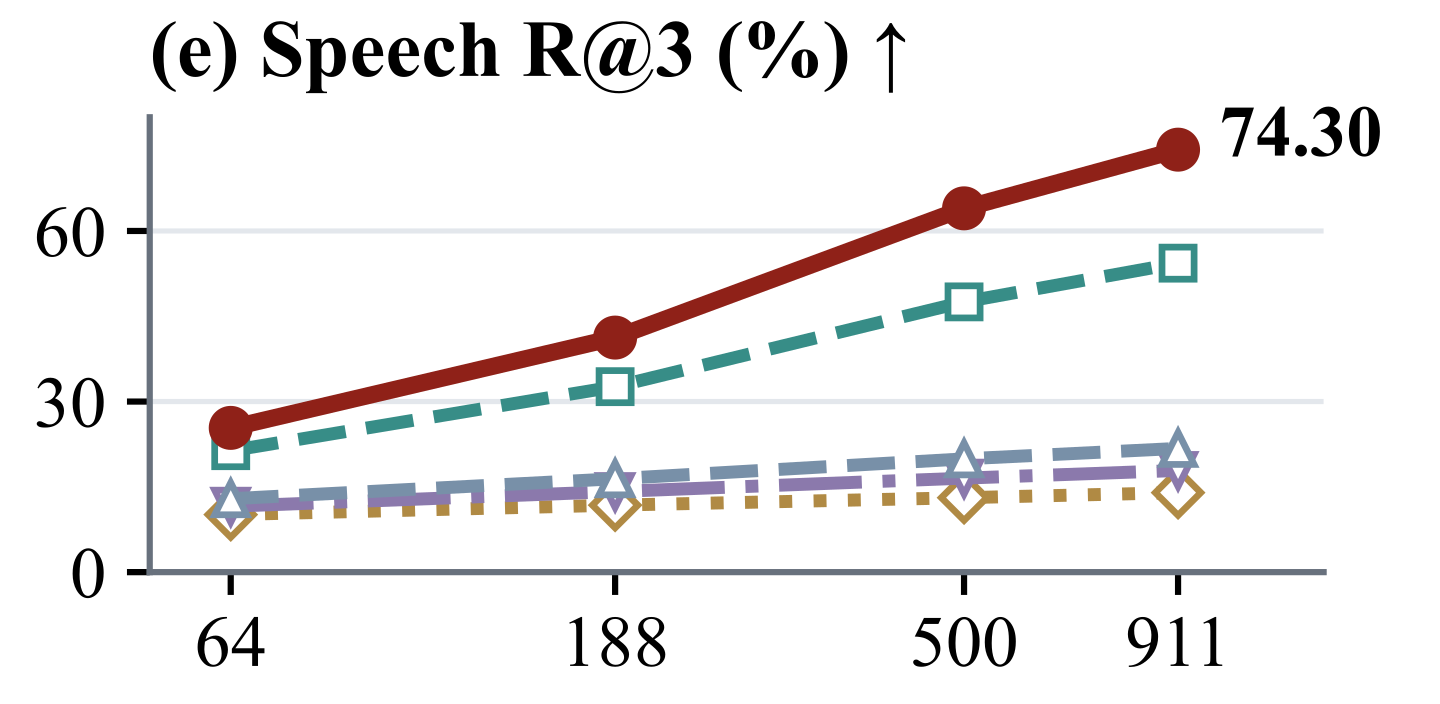
Action-expert parameters · millions · log scale
10% → 100% training data
More data, greater gains.
Relative improvement in Speech R@3 at each fixed model size.
Rounded percentages as reported in the paper.
Data × model size
Tracking score
1%3%10%30%100%training data
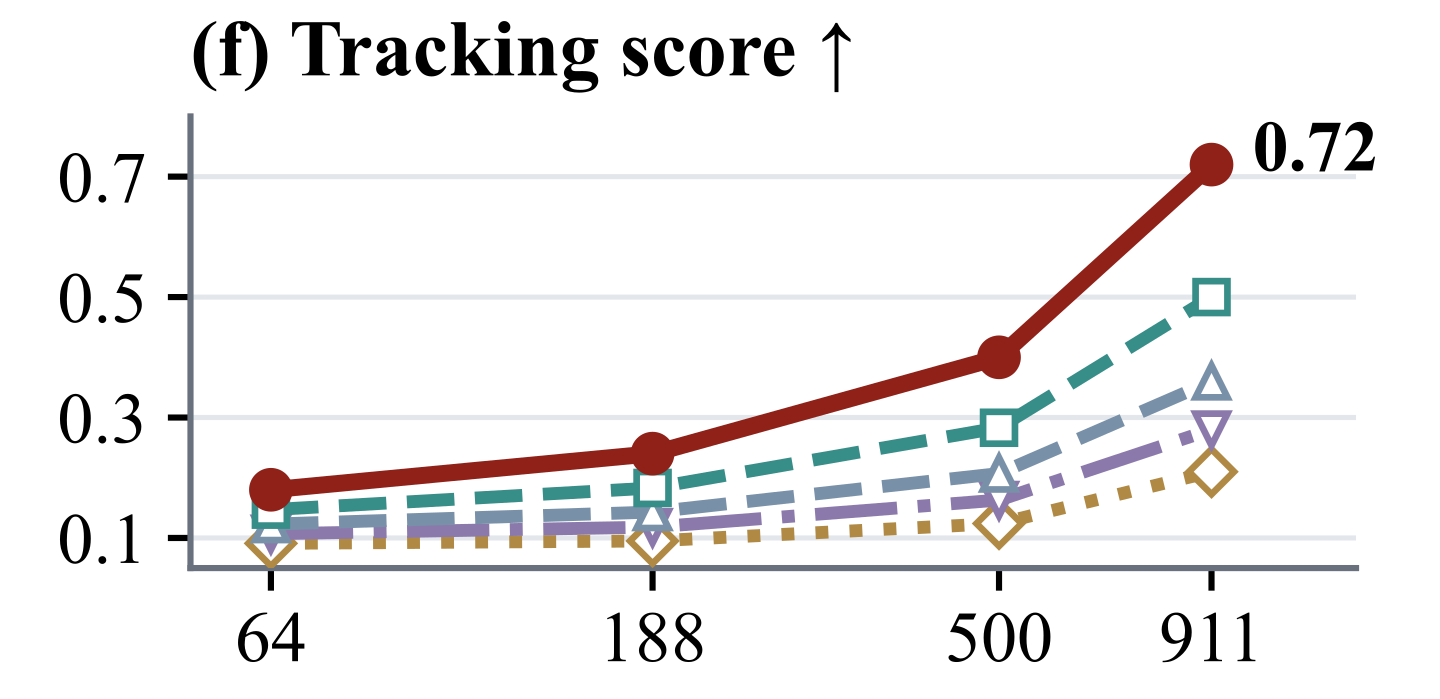
Action-expert parameters · millions · log scale
10% → 100% training data
More data, greater gains.
Relative improvement in Tracking score at each fixed model size.
Rounded percentages as reported in the paper.
06 / Capability showcase
Five ways to express intent. One shared motion model.
Explore a curated set of real-robot demonstrations across live video, Internet video, speech, music, and text.
Video / Live
Real-robot demonstrationsFollow a performer as the motion unfolds.
Movens-Zero uses the current video stream and the robot’s latest state to continuously replan executable whole-body motion.
Real-time video input · 01
Real-time video input · 02
Real-time video input · 03
Real-time video input · 04
Real-time video input · 05
Real-time video input · 06
Video / In the wild
Real-robot demonstrationsBring human motion from the Internet onto the robot.
In-the-wild references provide locomotion, gesture, rhythm, and direction changes that the model translates into continuous humanoid behavior.
Internet video input · 01
Internet video input · 02
Internet video input · 03
Internet video input · 04
Internet video input · 05
Internet video input · 06
Audio / Spoken instruction
Real-robot demonstrationsSay what to do—and how to do it.
Spoken instructions specify actions, body side, repetition, order, and duration, from left-leg lunges to alternating waves.
Speech input · 01“Open your arms wide then cross them in front of your chest”
Speech input · 02“Do ten left-leg lunges”
Speech input · 03“Salute with your left hand”
Speech input · 04“Strike a few bodybuilding poses”
Speech input · 05“Alternate waving your left and right hands up to your head”
Speech input · 06“Wave your left hand for seven seconds”
Audio / Music
Real-robot demonstrationsLet sound shape the movement.
Music conditions the timing and character of coordinated footwork, balance shifts, turns, and upper-body motion.
Music input · 01
Music input · 02
Music input · 03
Music input · 04
Music input · 05
Music input · 06
Language / Text
Real-robot demonstrationsTurn a prompt into a whole-body behavior.
Natural-language prompts can describe an action, a path, or a style—from counted squats and counterclockwise walking to salsa and zombie motion.
Text input · 01“Dance some hip-hop”
Text input · 02“Do three squats”
Text input · 03“Perform a salsa dance”
Text input · 04“Walk counterclockwise”
Text input · 05“Walk forward and wave”
Text input · 06“Act like a zombie”
07 / Citation
Build on Movens-Zero.
The technical report will be linked when released. Code, model checkpoints, and the public dataset are available now.
@article{bu2026movenszero,
  title   = {Movens-Zero: Scaling Humanoid Motion Foundation Models with
             Large-Scale Human Videos},
  author  = {Wendong Bu and Tinghong Ye and Qizhou Wang and Jiacheng Li and
             Zhiqi Ge and Yuze Lin and Zhongqi Yue and Yi Su and Jingyu Wang and
             Kai Shen and Jingdong Liu and Chengyuan Deng and Xiaoxuan Chen and
             Xin Tan and Jiaming Ji and Wenqiao Zhang and Chenghong Jiang and
             Tuoyu Li and Siliang Tang and Jun Xiao and Tat-Seng Chua and
             Yueting Zhuang and Xingxing Wang and Juncheng Li},
  journal = {Technical Report},
  year    = {2026}
}